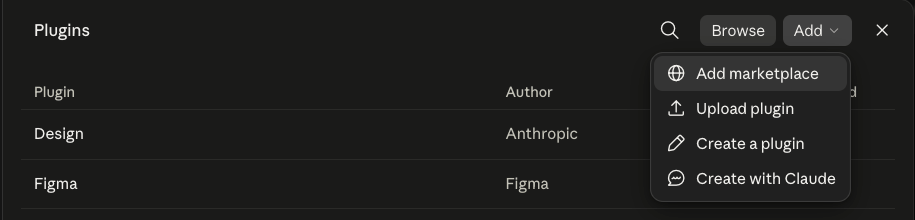
Install the plugin and Claude sets the connection up with you. No terminal at any point.Open Settings → Plugins, then Add → Add marketplace:
The Add menu in Claude's Plugins settings
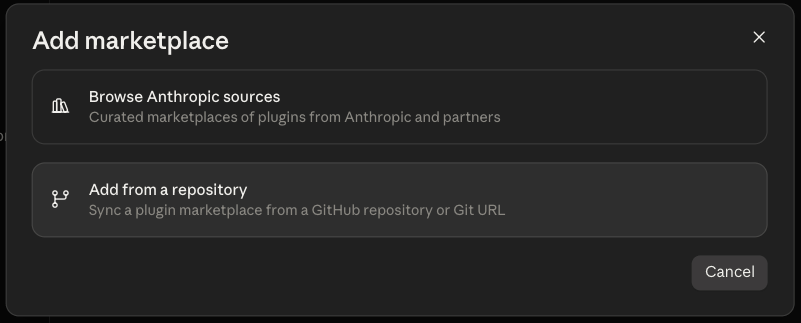
Choose Add from a repository and paste https://github.com/Creatorline/skills — the
dialog wants the full address, not the owner/repo short form the CLI takes:
Adding the marketplace from its repository
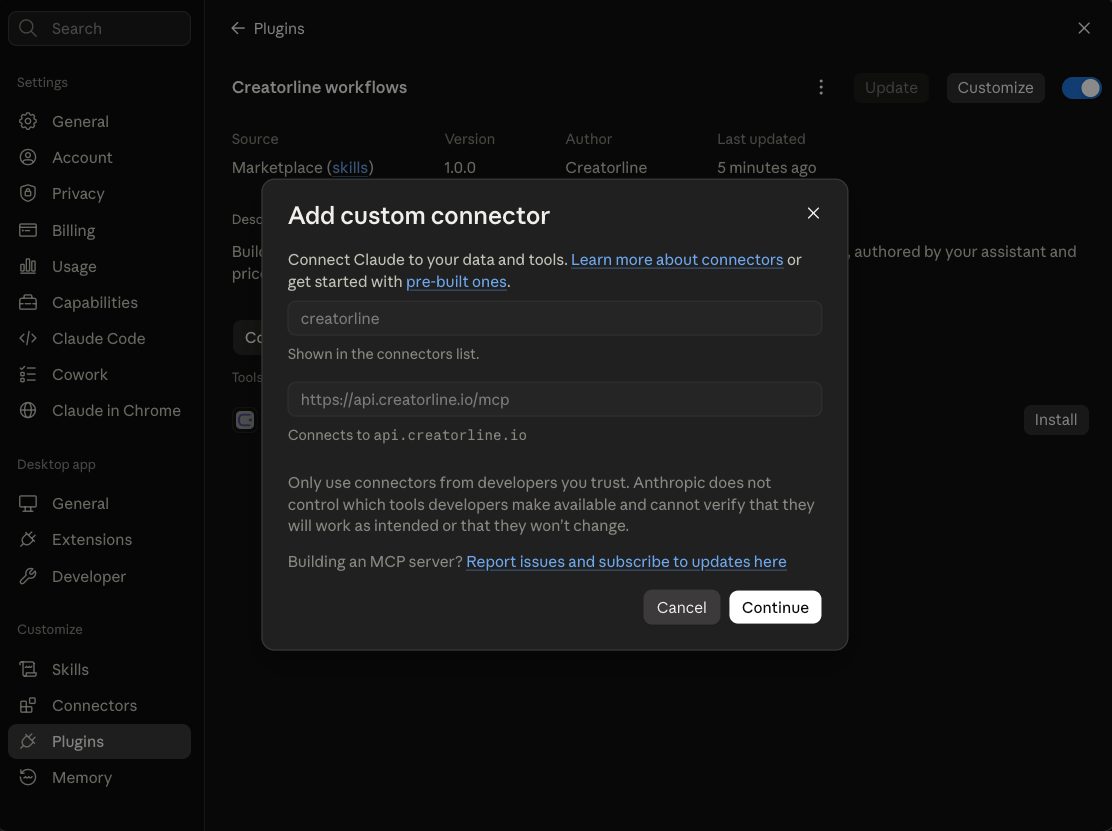
Then install Creatorline workflows. It carries the MCP server and the workflow skill
together, so the address arrives already filled in.
The connector Claude offers when the plugin installs
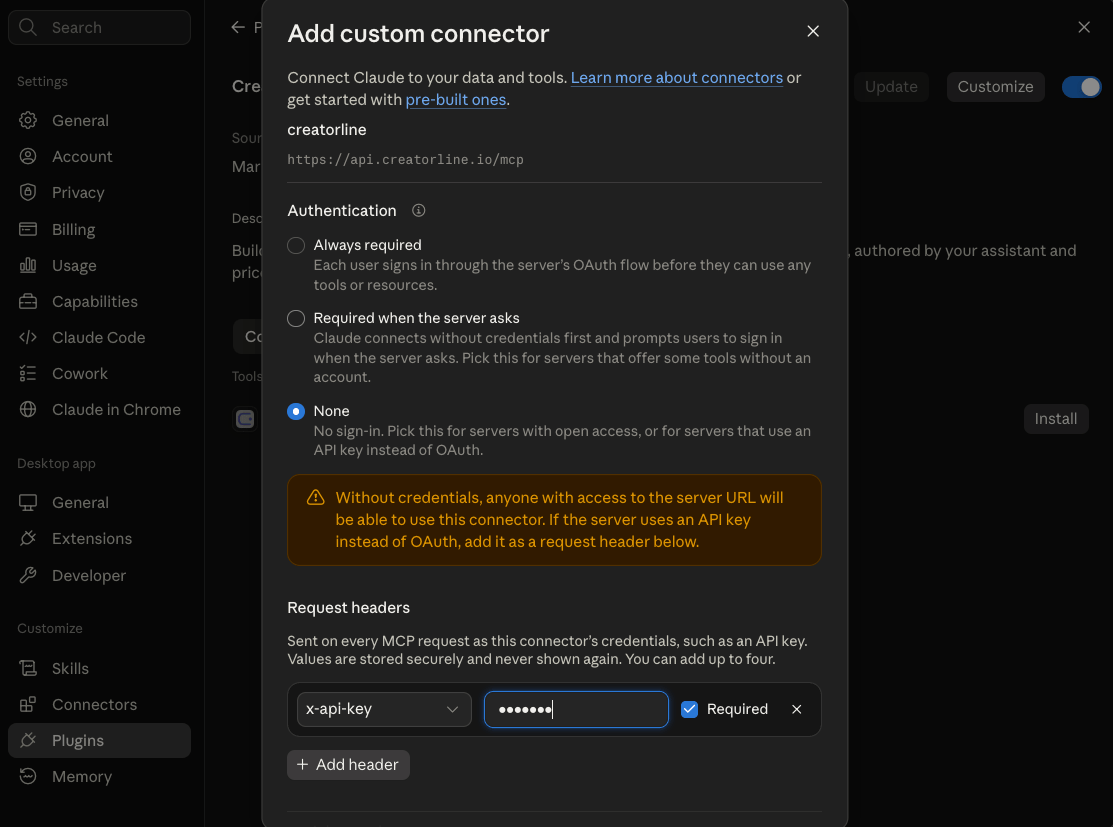
Under Authentication choose None — the server takes an API key, not a sign-in.
Then add a request header, pick x-api-key, and paste a key from Settings → API.
Authentication set to None, with the key added as an x-api-key header
x-api-key rather than authorization: the dialog sends these headers alongside its
own OAuth bearer token, and a header you own outright cannot collide with one the
client sets. The server reads either.
Verify with claude mcp list, then /mcp inside a session to inspect tools.
Set timeout to at least 60000. Claude Code applies a 60-second first-byte timer to HTTP MCP servers and a 5-minute idle timer; the default is too tight for a video run’s first poll.
Codex CLI (OpenAI) reads ~/.codex/config.toml. HTTP MCP servers live under [mcp_servers.<name>] with experimental_use_rmcp_client = true:
Prefer the CLI to write the config for you: crl mcp config prints the snippet for your harness, and crl mcp install runs claude mcp add on your behalf.
Nineteen coarse tools, not one per model. A tool per model would consume an agent’s context for no benefit; instead create_generation takes a tool and the model schema comes from list_models — which returns each model’s full shape: every input slot with its cap, every parameter with its allowed values or numeric bounds, what opaque values mean, whether a prompt is required, and how long a take can be. list_voices covers the one thing the catalog cannot enumerate, the live voice list the audio tools take.
list_models for the catalog, list_accounts for the creators. Never guess an id.
2
Price it if the user asked
estimate_generation_cost is free and does not start anything. Give it the same inputs / source_url the real run will use: the source-billed tools (lipsync, motion-control, scene-video, change-voice, short-clip) charge per second of the source, so an estimate without the media is only a default-length guess.
3
Start and poll
create_generation returns a job handle immediately and reports the credits it charged. Poll get_generation every few seconds — a video takes minutes, and holding the tool call open would hit the client’s idle timer.Beyond tool / prompt / inputs / params, it carries source_url (work from a video link, for a tool whose catalog entry has accepts_source_url) and include_account_avatar (set false when the creator must not appear in the output).
4
Publish only on request
create_post puts a post in the review queue. publish_post makes it public — it is annotated as destructive so your client prompts first, and the tool description tells the model to confirm with the user.create_post carries the full composition: format, hashtags, draft, made_with_ai, physical_device, auto_add_music, photo_cover_index and per-platform overrides in platform_settings. See Publishing for what each one does. A setting the platform cannot take comes back as a plain-English error the model can act on, rather than a post that publishes wrong.Two of those have prerequisites the model cannot see, so both fail loudly instead of quietly: draft needs every targeted channel to support drafts, and physical_device needs the workspace’s phone posting enabled plus a creator bound to a device. publish_post then hands the post to every destination it carries, the connected channels and the bound phone alike.
A workflow is the studio’s reusable pipeline: generation steps wired into each other, optionally ending in a publish step, run by hand, from an agent, or on a weekly schedule. The eight workflow tools author and run the same graphs the canvas does, validated by the same rules, so a workflow built over MCP opens on the canvas and a workflow drawn on the canvas reads back over MCP.
1
Read the vocabulary
get_workflow_catalog lists every stage a step can be (photo, photo-edit, video-ref, video-i2v, scene-video, lipsync, merge-clips, …), the models each offers, and the full shape of each model: input slots with their modality, params with allowed values, whether a prompt is required, whether it may run verbatim, take length and price. Pass stage to keep the answer small. Never guess a stage, model or slot id.
2
Write the graph
A graph is nodes plus edges. A generation node is { id, kind: "generation", stageId, modelId?, prompt, params, slotBindings? }. A publish node is terminal; its prompt is the caption. A text node is a named list of values that any prompt reads as @name; an image node is a list of asset ids wired into one slot. An edge is { source, target }; handles default to the source’s output modality (image, video, or audio for the speech steps) and the first matching slot on the target.Two params are the composer’s, not the model’s. enhance: false sends your prompt to the provider exactly as written, with no AI rewrite, no persona and no template, which is what you want when the prompt is already final. inject_persona: false keeps the creator’s persona out of a composed prompt.
3
Validate for free, then save
validate_workflow returns every problem at once (unknown ids, a modality mismatch, a cycle, a publish node with an outgoing wire), the step order, the model each step will really execute and the cost of a full run. Iterate until ok is true, then create_workflow with the same nodes and edges. Bind an account_id so steps inherit the creator’s look and a publish step knows whose channels to use.
4
Run and poll
run_workflow with dry_run: true reports the plan without spending. Without it, it returns a run handle and charges each step as it executes; poll get_workflow_run for per-node state, output URLs and credits. only_node_ids runs a subset, reuse_from_run_id serves unchanged steps from an earlier run. A publish step lands the post in the review queue as pending_review; nothing goes public from a workflow.
Porting a pipeline from another tool? Install the creatorline-workflows skill in your agent: it carries the graph grammar, the quality ladder per stage and a porting playbook, so the agent builds the right graph on the first try.
The workspace comes from the API key, never from a tool argument. There is no workspace_id parameter anywhere in the tool surface, so a model cannot be talked into reading another organization’s data.A read-scope key gets a plain-English refusal from the writing tools rather than a protocol error, so the agent can explain the problem instead of retrying.
The server implements the 2026-07-28 MCP revision: no session id, no handshake, no resumable streams. Every request builds a fresh server instance bound to the calling key. In practice that means it never gets into a bad session state, it scales horizontally, and reconnecting costs nothing.
Putting the key in the URL instead
https://api.creatorline.io/mcp/<key> is the identical endpoint with the key read off the path: same parse, same constant-time comparison, same revocation, expiry, scope and rate limit. It exists for clients that accept nothing but an address.Prefer a header wherever one is offered. A URL is written to proxy logs and browser history, and it travels whole when somebody pastes it into a chat; a header is not and does not. If a connector URL does leak, revoke that one key — which is the argument for minting a key per connector rather than reusing one.OAuth is still the destination, and it retires the path form entirely.
Media comes back as URLs, never inline. Lists default to 20 rows and page. Claude Code truncates tool output at 25,000 tokens, so the tools are built to stay well under that — if you need everything, page rather than raising the limit.